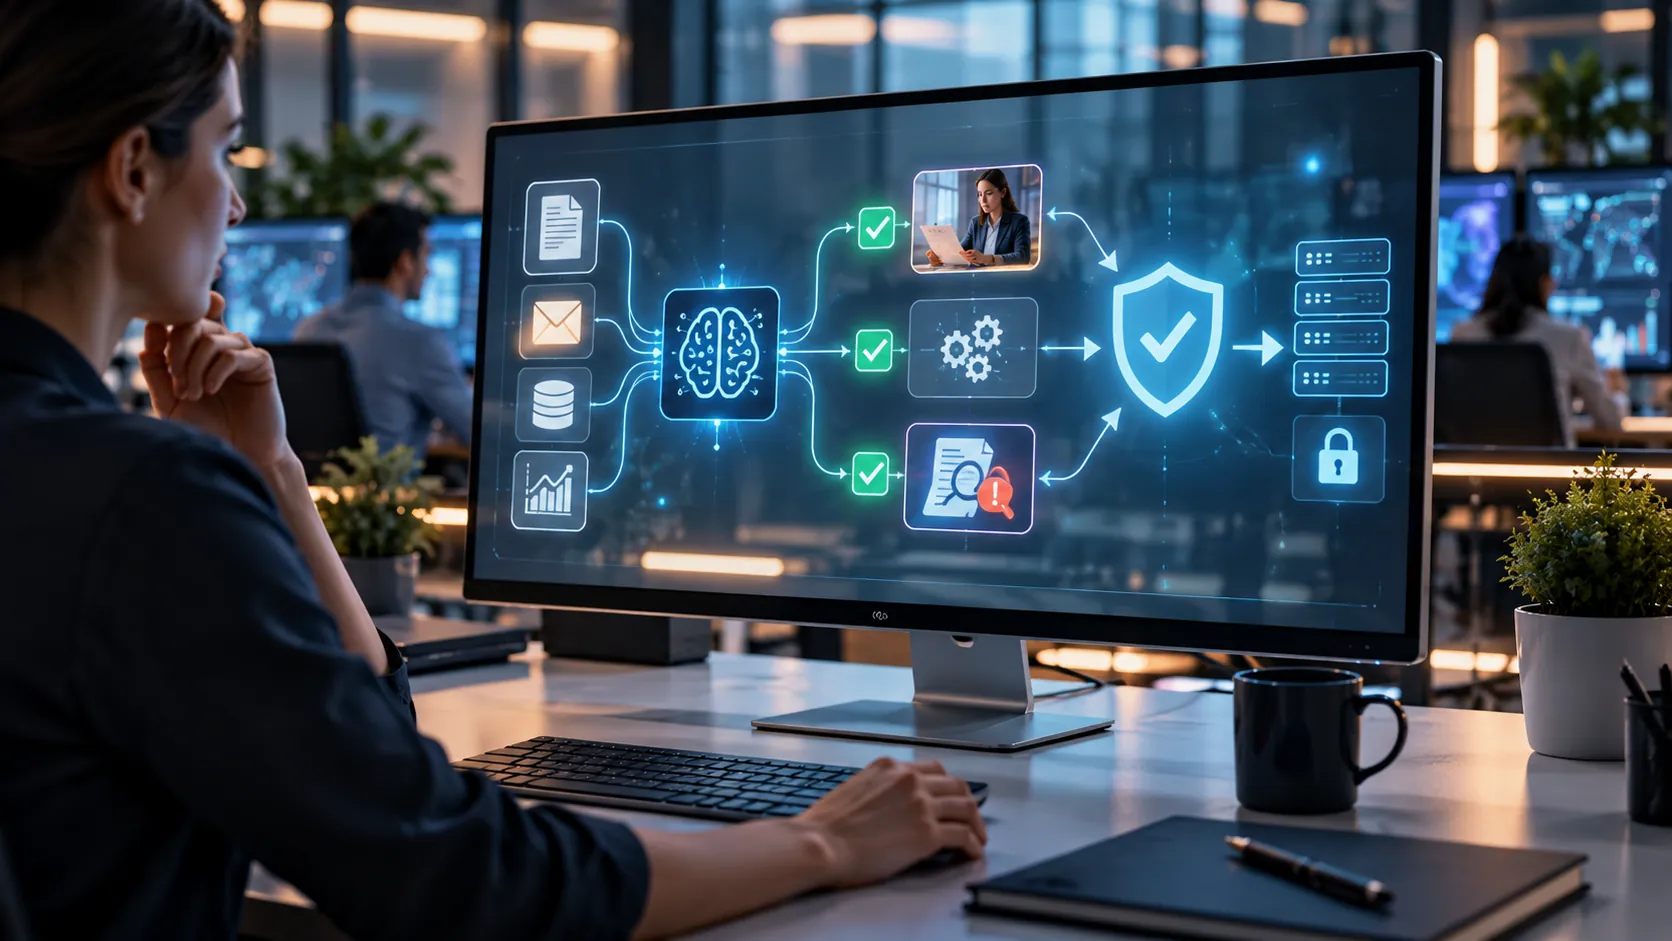
Trust in AI workflows comes from boundaries, data controls, evidence, evaluation, human review and an audit trail—not confidence in generated text alone.
Trust is a property of the system
A model that produces fluent text is not automatically safe to place inside a business process. Trustworthiness depends on what the entire workflow can access, what it is allowed to change, how its output is checked and how errors are handled. A summarizer working from public articles needs different safeguards from a system drafting customer refunds.
The NIST AI Risk Management Framework treats risk management as an ongoing organizational activity. That is a useful starting point: the goal is not to declare that a model is trustworthy forever, but to make evidence-based decisions about a particular use in a particular context.
Start with boundaries and permissions
Define the job in operational terms. Identify the inputs, outputs, tools, data owners and any irreversible actions. If an AI assistant only needs to read a support ticket and recommend a category, it should not automatically receive permission to delete tickets or send external messages.
Least privilege matters because a mistaken or malicious instruction is far less damaging when the system lacks broad capabilities. Keep read operations separate from writes, use scoped credentials and require explicit approval before sensitive actions. Treat content retrieved from email or documents as data, not instructions that can override your application rules.
Evidence, uncertainty and source quality
For questions about organizational policies, prices or customer records, the workflow should draw from approved data and ideally show what supported the answer. A useful answer can be “the source did not specify this,” rather than a polished guess. Source references should be checked for relevance, freshness and access restrictions.
Retrieval improves grounding only when the retrieved material is itself reliable. An outdated policy document can produce a confidently wrong recommendation. Assign ownership for source maintenance and build expiration or revalidation rules for information that changes frequently.
Evaluation before and after deployment
Use a small but representative set of cases to establish how the workflow behaves. Include normal requests, missing data, conflicting instructions, malformed input and content attempting to manipulate the assistant. Measure outcomes that matter to the process: accuracy against reviewed examples, time to review, percentage of escalations and consequences of errors.
Once deployed, monitor examples of failure, drift in the input data and changes in model behavior. Save enough information to investigate incidents while minimizing personal data retention. Without a feedback loop, teams may mistake early demos for durable production quality.
Human review is a design choice, not a weakness
Different steps deserve different gates. Drafting a suggested tag for a ticket may be low risk; sending a legal commitment or making a financial decision is not. A reviewer should see the proposed action, relevant evidence and possible impact, not just a mysterious green “approve” button.
A human-in-the-loop step should be recorded and recoverable. If the user rejects a suggestion, the workflow should stop or route to a correction step rather than silently continuing. This keeps responsibility visible and makes the process auditable.
Design for failure and recovery
External APIs time out, permissions change, models return unusable output and humans decline approvals. A trustworthy workflow has retry limits, idempotent actions, safe error messages and a way to resume after interruption without repeating a payment or sending the same email twice.
Use the smallest system that solves the problem. Sometimes a rules engine and a validation step are more reliable than an autonomous agent. The key is to choose the level of intelligence that matches the uncertainty of the task, and pair it with controls proportional to the stakes.